On May 21, 2026, the Cloud Native Computing Foundation announced what many practitioners had already suspected: OpenTelemetry had graduated. The milestone made it official — after seven years of development, mergers, and community building, OTel stands alongside Kubernetes, Prometheus, and Envoy as a CNCF graduated project. In the months since, the conversation has shifted from celebration to a harder question: now what?
The answer matters more than the ceremony. OpenTelemetry’s graduation is not merely a seal of approval. It is a signal that observability has crossed the threshold from experimental tooling to foundational infrastructure, and the organizations that treat it as optional will find themselves unprepared for the workload demands already arriving at their door.
What Graduation Actually Means
CNCF graduation is not a popularity contest. Projects must demonstrate production adoption, robust governance, community health, independent security audits, stable APIs, and comprehensive documentation. OpenTelemetry cleared all of these, and the evidence is measurable: over 12,000 contributors from more than 2,800 companies, across language-specific Special Interest Groups that span nearly every major runtime.
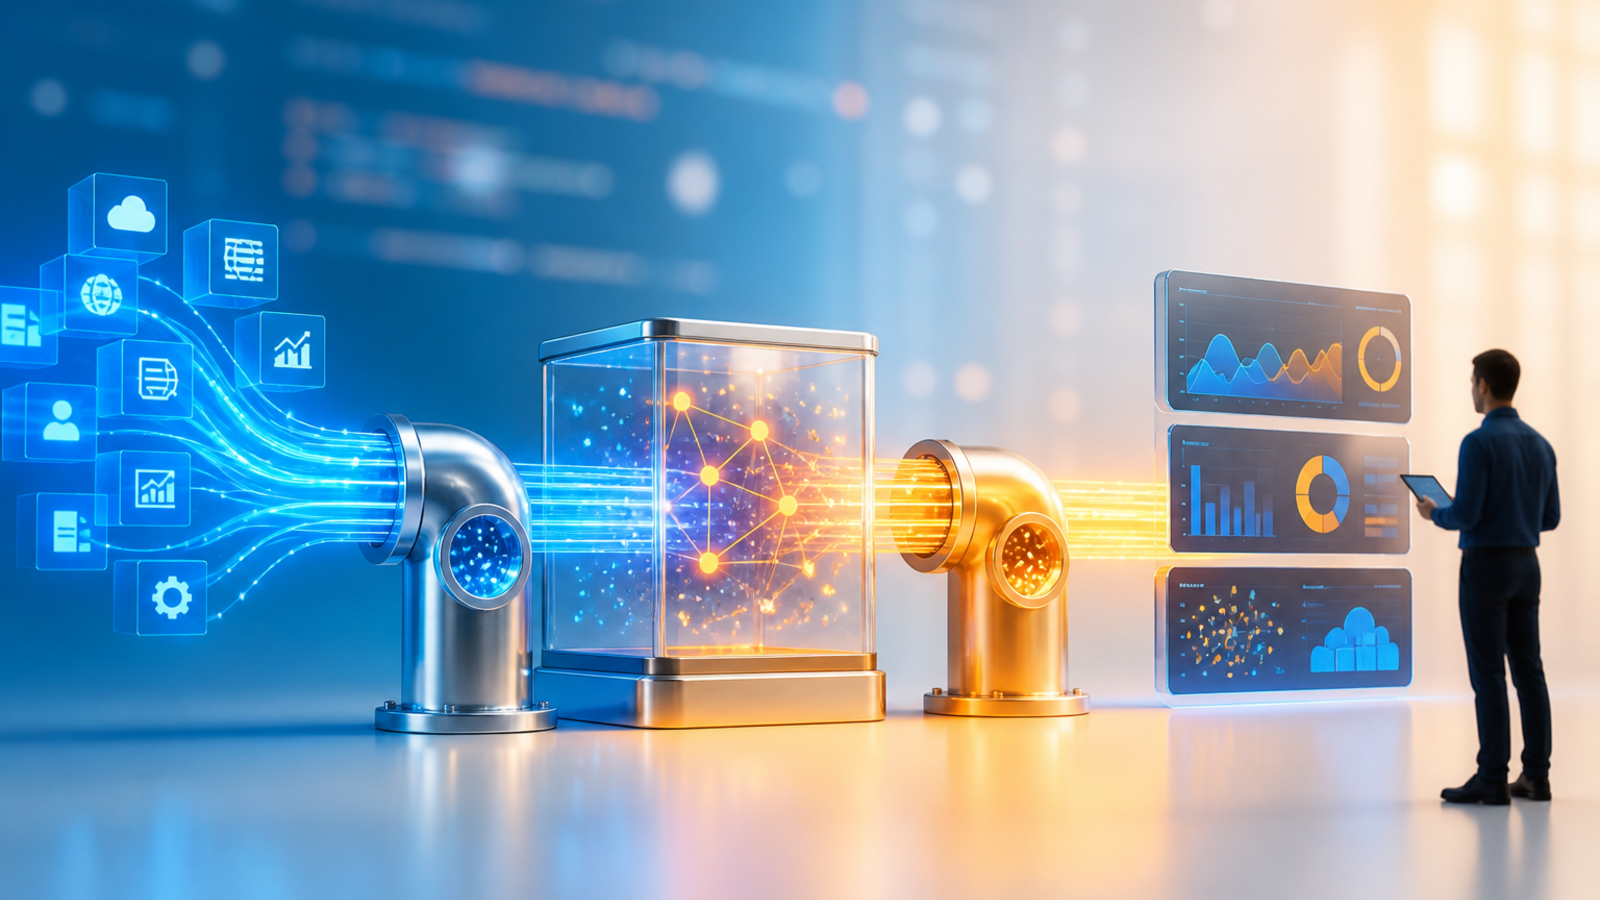
But the real indicator is adoption. GitHub runs OpenTelemetry in production. So do Farfetch, Shopify, and a growing roster of enterprises that do not publicize their internal stacks. The telemetry signals — traces, metrics, logs, and the newly added profiling — are no longer vendor experiments. They are standardized, correlated, and instrumented through a single pipeline that the OpenTelemetry Collector can route anywhere.
This standardization resolves a problem that plagued observability for years. Before OpenTelemetry, switching between monitoring vendors required ripping out instrumentation libraries and replacing them with new ones. Telemetry formats were proprietary. Correlating a metric spike with the trace that caused it required vendor-specific glue. OpenTelemetry’s unified data model, built from the merger of OpenTracing and OpenCensus, replaced that lock-in with interoperability.
For platform teams, the practical effect is liberation. You can instrument once and route to any backend — whether that is Prometheus for metrics, Jaeger for traces, or a commercial observability platform. The cost of switching drops dramatically. The cost of not instrumenting rises just as fast.
Why the Timing Matters
OpenTelemetry’s graduation arrived at a moment when cloud-native infrastructure is being reshaped by artificial intelligence. The CNCF blog post “How cloud native goes AI native,” published September 9, captures a tension that platform engineers are already living: the infrastructure that powers AI workloads is often built by agents and non-traditional developers who prioritize speed over operational rigor.
AI training jobs burst across clusters, consuming GPU resources in unpredictable patterns. Inference services require autoscaling that responds to user-facing latency, not just CPU utilization. Data pipelines sit adjacent to application workloads, demanding isolation and shared visibility. And yet, as Doron Grinstein argues in that post, the default AI-native infrastructure stack is frequently a stripped-down version of cloud-native best practice — one that drops mutual TLS, least-privilege identity, and telemetry because those concerns do not show up in demos.
This is where OpenTelemetry’s maturity becomes urgent. An AI workload running without observability is a workload you cannot optimize. You cannot tell whether your GPU scheduler is fragmenting resources. You cannot correlate an inference latency spike with a container restart. You cannot distinguish between a model degradation event and a networking partition. Without telemetry, AI infrastructure is opaque infrastructure, and opaque infrastructure is expensive infrastructure.
The New Signals: Beyond Metrics, Logs, and Traces
OpenTelemetry’s scope has expanded well beyond the three pillars of traditional observability. Profiling joined the signal set in 2024, giving teams visibility into CPU and memory hot paths at production scale. The OpenTelemetry Operator now provides Kubernetes-native deployment of collectors and auto-instrumentation. OpAMP, the Open Agent Management Protocol, allows remote configuration of telemetry agents without redeploying workloads.
These additions matter because modern workloads are no longer simple request-response services. A single AI inference call may traverse a model server, a vector database, an embedding service, and a caching layer, each emitting different telemetry types. The collector’s ability to receive, transform, and export all of these signals through a unified pipeline is what makes comprehensive observability feasible at scale.
OTel Arrow, a columnar protocol optimized for high-throughput telemetry transport, addresses another emerging bottleneck: the sheer volume of data that AI and microservice architectures generate. Standard OTLP is efficient; OTel Arrow is designed for environments where millions of spans per second are routine. The project is already thinking about the next order of magnitude before most teams have reached the current one.
What Platform Teams Should Do Now
For teams that have already adopted OpenTelemetry, graduation changes little in day-to-day operations. The APIs were already stable. The collector was already production-hardened. The community was already responsive. What changes is organizational confidence. Procurement teams that previously required vendor-specific telemetry agents can now point to a graduated CNCF standard. Security teams that questioned the maturity of open-source instrumentation can reference an independent audit. Engineering leaders can invest in OTel expertise without worrying that the project will evaporate.
For teams that have not yet adopted OpenTelemetry, the window for delay is closing. The ecosystem is large enough that first-class support exists for nearly every language and framework. The documentation is comprehensive enough that onboarding no longer requires reading source code. And the community is active enough that edge cases are resolved quickly.
The specific actions are straightforward:
- Instrument your applications with the language-specific OpenTelemetry SDKs. Start with tracing, then add metrics and logs as your comfort grows.
- Deploy the OpenTelemetry Collector as a central pipeline for receiving, batching, and exporting telemetry. Use its processor plugins to filter noise before it reaches your backend.
- Correlate signals by ensuring that trace IDs, span IDs, and resource attributes are consistent across services. This is what turns three separate data streams into a single coherent story.
- Add resource attributes for workload identity — cluster name, namespace, deployment version, team label — so that telemetry is queryable by the dimensions that matter to your organization.
- Plan for profiling as a follow-on phase. It requires more overhead than traces or metrics, but the insight into hot-path code is worth the investment for latency-sensitive services.
The Broader Implication
OpenTelemetry’s graduation is part of a larger pattern in the cloud-native ecosystem. Kubernetes proved that orchestration could be standardized and vendor-neutral. Prometheus proved that metrics collection could be. Envoy proved the same for proxying. OpenTelemetry has now done it for observability.
The result is a stack where every layer — compute, networking, storage, and now telemetry — has a graduated, community-driven standard. This does not eliminate commercial vendors. It changes their role. Vendors now compete on analysis, visualization, and operational workflows rather than data lock-in. The telemetry itself belongs to the user.
As AI workloads continue to strain infrastructure, this ownership will matter more. The teams that can observe their systems — truly observe them, across traces, metrics, logs, and profiles — will be the teams that can optimize them. The teams that cannot will pay the price in cloud bills, incident duration, and missed service-level objectives.
OpenTelemetry is no longer the future of observability. It is the present. Graduation simply made it official.