Google has released Agent Substrate 1.0, made the software generally available as a managed capability on Google Kubernetes Engine, and begun moving the open-source project into the Cloud Native Computing Foundation’s Sandbox. The milestone arrives with a clear argument about the next Kubernetes workload: autonomous agents need containers when they are working, but they should not occupy a Pod for every minute they remain alive.
That distinction matters because an interactive agent is not shaped like a conventional web service or batch job. It may execute generated code for seconds, wait for a model response, pause for an external API, and then sit idle until a person returns hours later. Kubernetes can keep such a process alive, but doing so at very large scale wastes memory and burdens the control plane with long-lived objects. Destroying the Pod saves compute, yet shifts the hard work of preserving memory, files, identity, and access policy back to the application team.
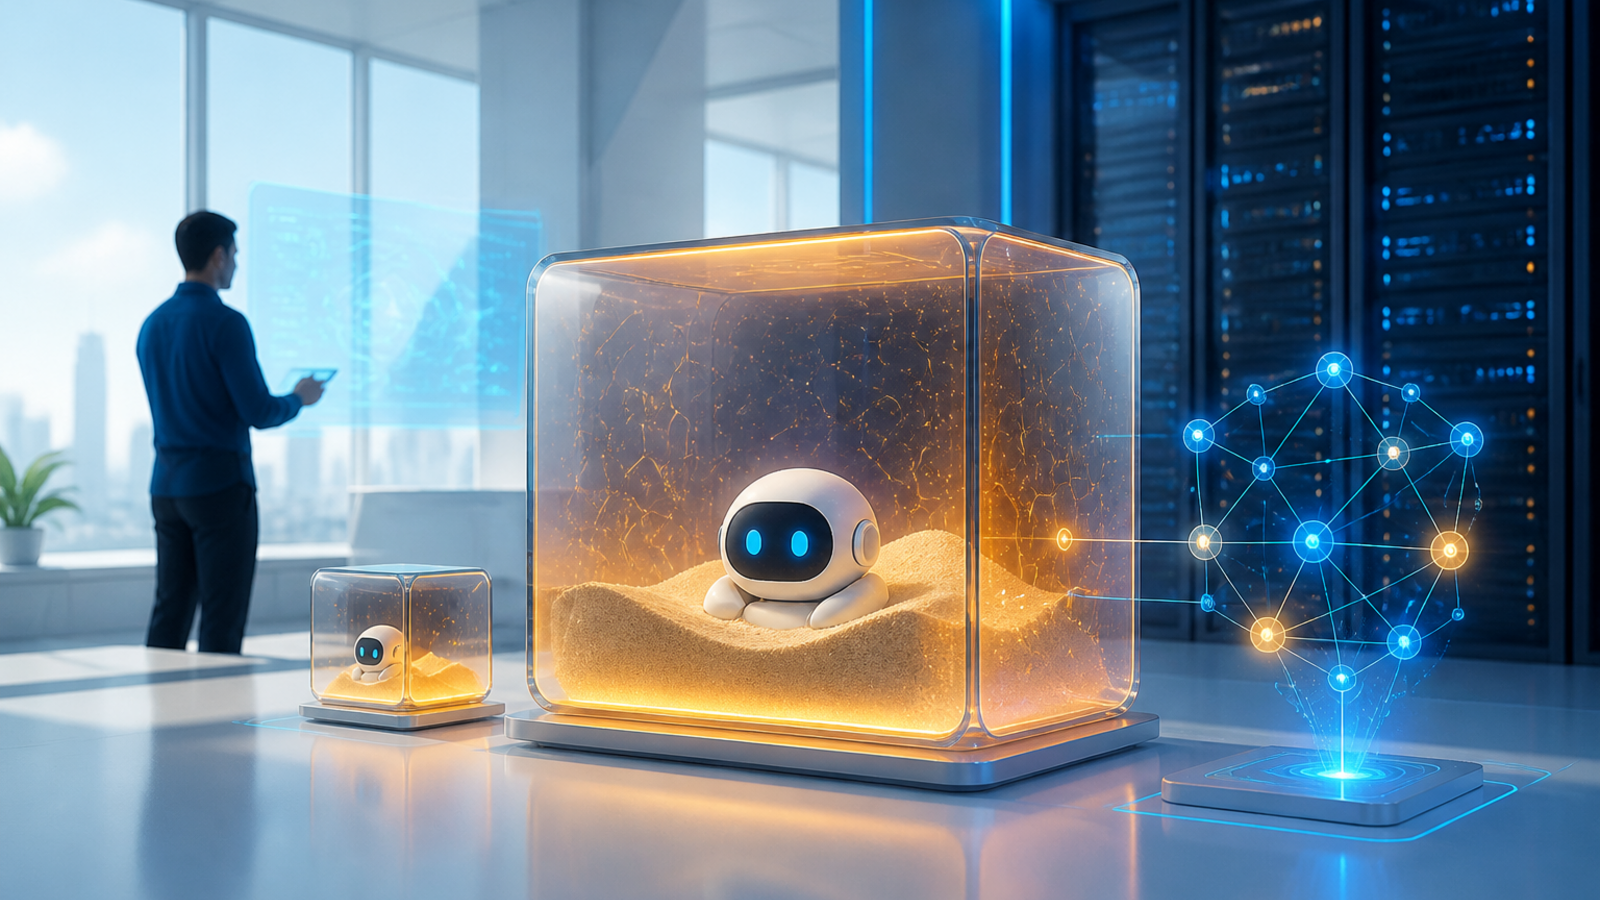
Agent Substrate proposes a third model: separate the durable agent session from the disposable execution sandbox. Its 1.0 release is important less as another AI add-on than as a test of whether Kubernetes can support stateful, intermittent work without equating identity and lifetime with a Pod. If that model proves portable under CNCF governance, it could give platform teams a reusable layer for coding agents, productivity assistants, and other workloads that spend more time waiting than computing.
The Pod is no longer the session
Agent Substrate divides the workload into a few distinct concepts. An Actor holds the agent’s memory, files, and identity. A Worker is an isolated sandbox that executes an active Actor. A WorkerPool keeps reusable execution capacity warm, while gateways mediate access based on the Actor’s identity.
When an Actor becomes idle, the system snapshots its memory and local files to storage and releases the Worker. When another request arrives, the system claims an available Worker, restores the snapshot, and resumes execution. Google says restoration takes less than 500 milliseconds and that the 1.0 system has demonstrated more than 500 suspend-and-resume activations per second. The company also claims ten times the density of standard container runtimes and operation across millions of sandboxes. Those are vendor-reported figures, not a universal performance guarantee, but they illustrate the design target: make a persistent session cheap while it is inactive.
The architecture does not replace Kubernetes. It uses Kubernetes to provision and manage pools of Workers while avoiding the requirement that the control plane represent every dormant agent as a running Pod. In effect, Kubernetes manages the execution fleet, and Agent Substrate manages the much larger population of logical sessions.
This is a meaningful boundary. Kubernetes is excellent at reconciling declared resources and scheduling active workloads, but a Pod is neither a hibernation format nor a durable user session. Agent Substrate acknowledges that mismatch rather than asking the scheduler to carry millions of mostly idle objects.
Why agent workloads expose the mismatch
Traditional services are commonly optimized around continuous availability. Batch systems are optimized around a job that starts, consumes resources, and finishes. Agent workloads combine traits of both while adding untrusted execution and long-lived conversational state.
A coding agent, for example, may maintain a working tree and in-memory process state across many interactions. It can install packages, run shell commands, start tests, and wait for a developer. A productivity agent may preserve context for weeks but wake only for an event. Keeping a dedicated sandbox resident for every such session produces poor utilization. Recreating the environment from an image for each turn reduces idle cost but increases latency and makes state management an application concern.
Snapshot-and-restore shifts the unit of persistence. The session survives independently of the machine and sandbox that most recently ran it. A warm pool absorbs activation spikes, while capacity can be sized against concurrent active work rather than total registered agents. For operators, that could make the difference between a fleet sized for millions of identities and one sized for the smaller number doing work at a given moment.
The economics resemble serverless computing, but the retained state is richer. The restored environment includes memory and local files rather than only a function invocation plus external data. That benefit also creates operational questions around snapshot size, storage throughput, restore tail latency, compatibility, and lifecycle policy. The headline sub-second restore is only one part of the service-level objective; a production system must also behave predictably when many sessions wake together.
Isolation and identity are part of the runtime
Density cannot come at the expense of containment. Agents routinely run model-generated commands and third-party packages, so ordinary container boundaries may be insufficient for hostile or simply unpredictable code. Agent Substrate supports gVisor and Cloud Hypervisor microVMs as execution boundaries. The former intercepts application system calls in a userspace kernel; the latter offers a hardware-virtualized boundary where suitable infrastructure is available.
The timing of gVisor’s own move toward CNCF governance is therefore more than organizational housekeeping. gVisor is a critical dependency for users who want stronger isolation at container-like density without relying on nested virtualization. Its maintainers say neutral governance could also improve prospects for upstreaming Linux kernel changes that address I/O performance. Broader maintainership from organizations including Ant Group, Modal, and Tines should reduce the perception that the runtime is controlled for one cloud’s priorities.
Agent identity is equally important. A disposable Worker should not carry a broad, durable credential merely because an Actor may be restored there. The Agent Substrate design places policy enforcement at gateways and associates authorization with the Actor, allowing secrets to be provided for a specific request rather than embedded permanently in the sandbox. That is the correct security direction, but adopters will still need to validate audit trails, egress controls, snapshot encryption, tenant separation, and credential revocation in their own environment.
General availability comes with real constraints
The managed GKE path is now generally available, but it is not a drop-in feature for every cluster. Google’s current documentation requires GKE Standard rather than Autopilot, Kubernetes 1.37 or later, and Workload Identity Federation. The installer is incompatible with the Extended release channel because it enables beta APIs. MicroVM Workers require supported x86 nodes with nested virtualization or bare metal.
Other limitations are directly relevant to agent design. Open network connections are not preserved during suspension, so clients must reconnect to databases, model endpoints, and tool servers after resume. GPU passthrough into Actor containers is not currently supported, and gVisor cannot snapshot live CUDA contexts. Teams that mix interactive CPU work with accelerator-heavy execution may therefore need separate paths or explicit handoffs.
High density also moves pressure to less obvious parts of the host. Google warns that more than roughly 800 concurrent sandboxes on one node can exceed default Linux limits for inotify and ARP neighbor tables. The installer adjusts those settings for clusters it creates, but operators adding their own node pools must do the work themselves. Storage becomes part of the latency path because snapshots live in object storage, and observability overhead must be tested at the intended Pod and sandbox counts.
These constraints do not negate the model; they define its present maturity. “Millions of agents” describes the logical population the architecture aims to hold, not a promise that every existing Kubernetes cluster can enable it without capacity planning or application changes.
What platform teams should evaluate now
The open-source release runs on Kubernetes beyond Google Cloud, while GKE supplies optimized deployment tooling and a supported managed path. That split lets teams examine the architecture without immediately accepting cloud lock-in, but CNCF Sandbox status should not be mistaken for a mature portability certification. The onboarding process, independent build infrastructure, governance transition, and APIs still need time to settle.
A useful evaluation should start with workload behavior rather than an aspirational agent count:
- Measure the duty cycle. Record how long sessions compute, how long they wait, and how often they resume. The design offers the most value when idle time dominates.
- Benchmark restore distributions. Test median and tail latency with realistic snapshot sizes and synchronized wake-ups, not only isolated resumes.
- Exercise failure recovery. Kill Workers, interrupt snapshot transfers, rotate credentials, and verify that an Actor resumes once without losing or duplicating work.
- Model storage as infrastructure. Estimate snapshot volume, retention, encryption, regional placement, and object-operation cost alongside compute savings.
- Validate the isolation choice. Compare gVisor and microVM boundaries against threat models, performance needs, hardware constraints, and compliance expectations.
- Design reconnectable agents. Treat network sessions, leases, locks, and external tool calls as discontinuous across suspension.
Teams should also decide which state deserves to be snapshotted. Memory capture is convenient, but durable business state may be safer in an application database with explicit schemas and recovery semantics. Snapshots are best treated as execution continuity, not as the sole system of record.
A new layer in the Kubernetes stack
The most consequential part of Agent Substrate 1.0 is its claim that a logical workload can outnumber active Kubernetes objects by orders of magnitude. Kubernetes remains responsible for the available compute and its desired state, while another layer multiplexes stateful sessions over that compute. That pattern could become as important for intermittent agents as queue-backed workers became for asynchronous jobs.
Neutral governance will determine whether it becomes an ecosystem primitive or primarily a convenient route into GKE. The project needs multiple production implementations, portable conformance tests, stable interfaces, and credible participation from clouds and platform vendors beyond Google. gVisor’s parallel CNCF transition helps the isolation layer, but the wider stack must prove that its claimed openness survives operational differences among providers.
For Kubernetes practitioners, the immediate lesson is not that Pods are obsolete. It is that Pod lifetime is an expensive proxy for session lifetime when workloads are stateful, interactive, and mostly idle. Agent Substrate 1.0 supplies a concrete alternative: preserve the agent, recycle the sandbox, and let Kubernetes focus on the capacity that is actually working.