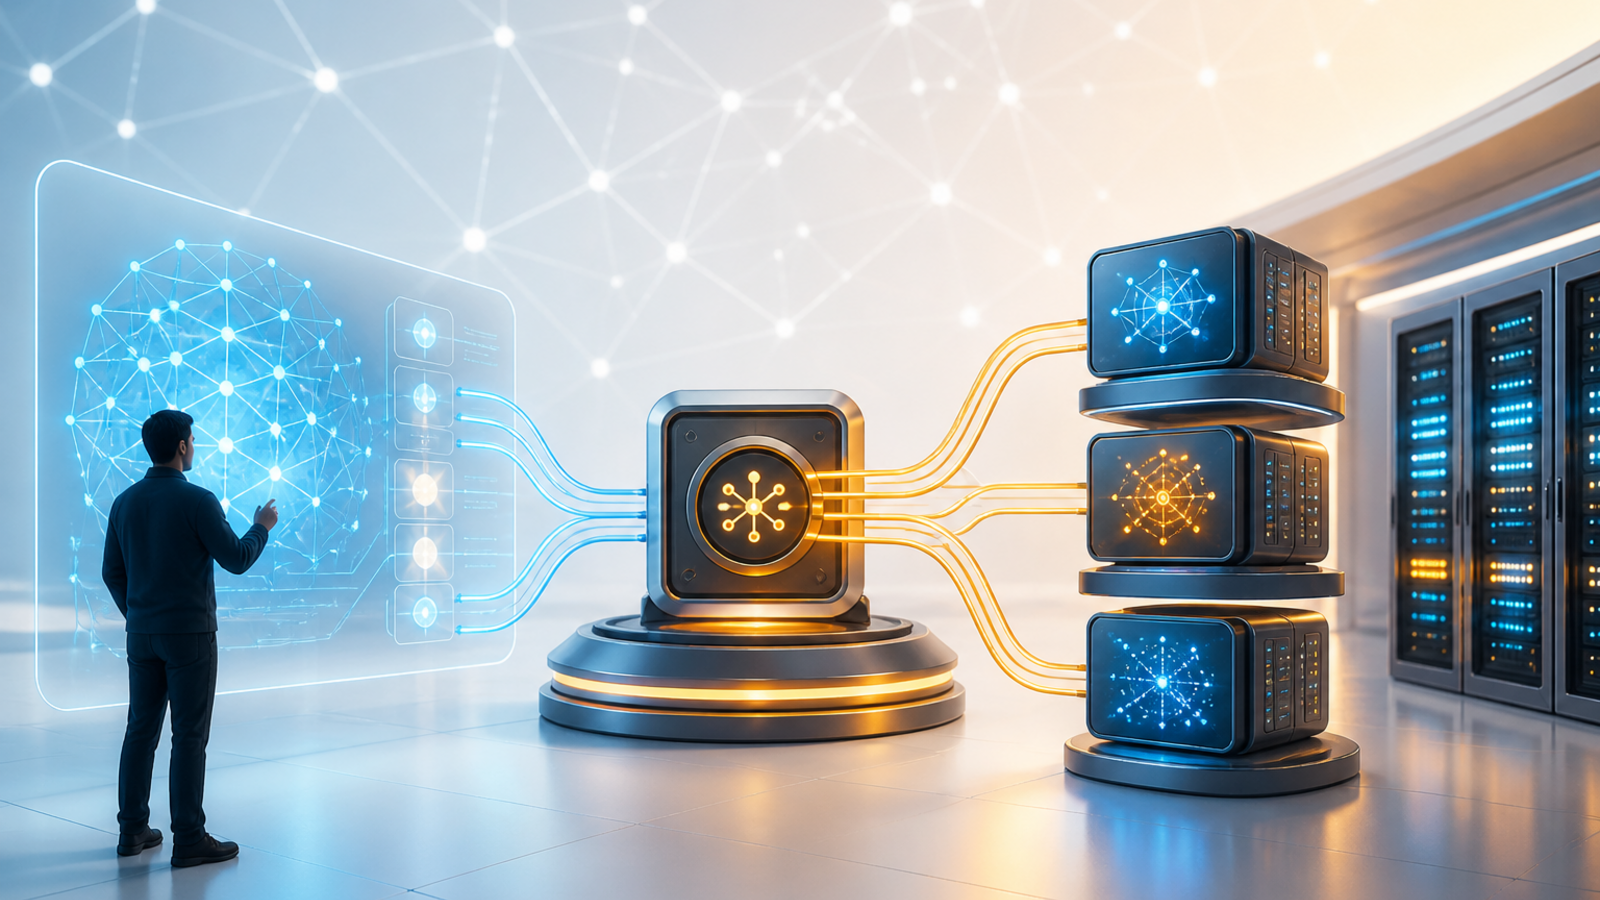
OpenAI’s API catalog now puts two GPT-6.2 models at the top of the general-purpose stack: GPT-6.2 Astra for the hardest projects and GPT-6.2 Sol as the lower-cost default. That looks like a familiar premium-versus-standard split. The infrastructure consequence is less familiar. Astra and Sol expose almost the same operational envelope—reasoning controls, tool access, a 1.05-million-token context window and 128,000 maximum output tokens—but their standard token prices differ by four times. When two models share an interface and differ sharply in cost, choosing between them stops being a configuration decision. It becomes a routing problem that platform teams need to measure, automate and govern.
The central lesson of GPT-6.2 is therefore not simply that a stronger model is available. It is that production AI systems can no longer treat “use the best model” as a complete deployment policy. The useful unit of optimization is the task, and the useful control plane must decide how much intelligence, context and latency each task deserves. Teams that build that control plane well can reserve Astra for work where its added capability changes the result while sending the broad middle of traffic to Sol.
A matched pair with a fourfold price gap
OpenAI describes GPT-6.2 Astra as its most capable model for difficult, end-to-end projects. Its model page says it can build and revise software, work with documents, use a computer and delegate to subagents through the Responses API’s multi-agent beta. GPT-6.2 Sol is positioned for a balance of intelligence and cost, with the same broad support for text and image input, tool use and subagent delegation.
The published specifications make the pair unusually easy to compare. Both list a 1,050,000-token context window, up to 922,000 input tokens and 128,000 output tokens. Both support the same reasoning-effort range from low through max, but neither accepts a reasoning effort of none. Both support functions, web search, file search, computer use, MCP, skills and tool search. Astra’s knowledge cutoff is listed as May 18, 2026; Sol’s is June 1, 2026.
Standard pricing is where the products separate. Astra costs $8 per million input tokens, $0.40 for cached input and $40 per million output tokens. Sol costs $2, $0.10 and $10 respectively. Cache writes are similarly divided at $10 for Astra and $2.50 for Sol for 30 minutes of retention. That clean four-to-one ratio makes the infrastructure question unavoidable: which requests actually earn the premium?
The answer cannot be derived from model names alone. An agent might spend most of its life classifying a ticket, extracting fields or checking whether a tool result satisfies a constraint, then occasionally face a multi-repository debugging task that benefits from a stronger planner. A blanket Astra policy pays the premium on every trivial step. A blanket Sol policy may save money but fail disproportionately on the few steps that determine whether the workflow finishes.
Context size is a capacity ceiling, not a routing strategy
A million-token context window invites a straightforward but dangerous design: put every available document, trace and conversation turn into every request. GPT-6.2’s pricing notes make clear why that is expensive. For requests above 272,000 input tokens, input and cache rates double and output rates rise to 1.5 times the short-context rate for the full request. The threshold is not merely a billing detail; it is an architectural boundary.
Astra’s short-context list price for 300,000 uncached input tokens is $2.40. Once the request crosses the long-context threshold, the input component becomes $4.80. The same request on Sol moves from $0.60 to $1.20. Output and tool-call costs add to that total. At agent scale, careless retrieval can dominate the bill before the model begins useful work.
Platform teams should make context construction observable as its own service. Record the tokens contributed by system instructions, conversation history, retrieval, tool schemas and attachments separately. Then ask whether each component improves completion quality. Summarization, scoped retrieval and state stored outside the prompt are not only prompt-engineering techniques; they are cost and reliability controls. The 272,000-token boundary should appear in dashboards and alerts just like a database saturation point.
Caching also deserves explicit design. On both Astra and Sol, cached input is priced at 5% of ordinary input, a substantial discount for repeated prefixes. Stable policies, tool definitions and reference material should be placed where the cache can reuse them. But cache writes have a price and retention period, so constantly changing a large prefix can erase the advantage. Measure cache-hit rate by workflow and model, and treat low reuse on large prompts as an optimization signal.
The router needs evidence, not intuition
A useful router begins with a small number of explainable rules and improves from observed outcomes. It does not need a second giant model to make every decision. Metadata already available at request time—workflow type, risk level, context length, tool count and prior attempts—can support a strong first version.
Define an eligibility envelope
Start by stating which work may use Astra. Good candidates include tasks with high recovery cost, long-horizon planning, ambiguous multi-step execution, complex software changes or repeated failure on Sol. Keep routine extraction, summarization, classification and bounded tool orchestration on Sol unless evaluation data shows a material quality gap.
Eligibility is not the same as automatic selection. A production policy can require both an eligible task type and a trigger such as high estimated complexity, a failed lower-tier attempt or a high-value customer workflow. This prevents casual premium-model use while still giving applications a predictable escalation path.
Escalate on signals that correlate with failure
Retries are the simplest signal, but they should be structured. An agent that receives invalid JSON does not necessarily need a more capable model; it may need constrained output or a validator. Escalation is more justified after failures involving planning, contradictory evidence, incorrect tool choice or inability to satisfy a multi-part acceptance test. Capture failure reasons in machine-readable form so routing policy can distinguish capability problems from application bugs.
Preflight signals can also help. A request spanning many files, several tools and a long acceptance checklist is more likely to benefit from Astra than a one-shot answer. Teams should validate those heuristics against real traces rather than assuming token count equals difficulty. Long requests can be easy, and short requests can hide costly ambiguity.
Budget the whole trajectory
Agent economics are measured per completed job, not per individual API call. Sol may be cheaper per token but more expensive for a workflow if it generates extra retries, longer outputs or unnecessary tool calls. Astra may justify its premium if it completes a valuable task in one trajectory. Conversely, using Astra for every internal planning step can multiply costs without improving the final outcome.
Track input, cached input, cache writes, output, tool charges and retry count under a shared job identifier. The key metric is cost per accepted outcome, segmented by route. Add latency and human-review time because a cheap route that creates a manual queue is not truly cheap.
A practical rollout plan
GPT-6.2 can be adopted without building a sophisticated reinforcement-learning router on day one. A disciplined staged rollout provides most of the value and produces the evidence needed for automation.
- Pin the initial routes. Send a defined set of high-volume, low-risk workflows to Sol and a narrow set of demonstrably hard workflows to Astra. Avoid a mutable “latest” assumption in evaluation records; log the exact model ID and all relevant parameters.
- Build a representative evaluation set. Sample real work across easy, typical and adversarial cases. Score task completion, constraint adherence, tool selection, latency and cost. A single aggregate accuracy number will conceal where the premium model matters.
- Shadow premium candidates. For a limited sample, run both models without exposing both answers to the user. Compare accepted outcomes and trajectory cost. Shadowing is expensive, so use it to answer specific routing questions and then stop.
- Add one escalation rule at a time. Begin with a clear trigger such as failed acceptance tests on an Astra-eligible workflow. Measure how often escalation recovers the job and what it costs.
- Set route-level budgets. Cap premium usage by workflow, tenant or environment. Alert on abrupt shifts in Astra share, long-context requests and cache-hit rate.
- Re-evaluate after prompt or tool changes. Routing results are coupled to the surrounding system. A better retrieval step or tool contract may allow Sol to handle work that previously required Astra.
Processing tiers add another routing dimension
Model selection is only one cost lever. OpenAI’s GPT-6.2 pages say Batch processing costs 50% of Standard rates. Fast mode costs twice Standard, while Ultrafast costs three times Standard throughout the supported context window. The correct route is therefore a pair: model and processing tier.
Offline enrichment, evaluation runs and backlog processing can often use Batch. Interactive agents may need Standard or a faster tier, but only where latency affects the product experience. A background research task should not inherit the same service level as a user waiting for a tool action. Encoding urgency separately from task difficulty prevents teams from paying for both premium intelligence and premium speed when only one is required.
This also changes capacity planning. Rate limits, batch queues and user-facing latency targets should be monitored per route. A fallback that silently moves traffic from Sol Standard to Astra Fast during an incident may preserve availability while creating a severe cost spike. Failover policy needs both a technical limit and a financial limit.
What GPT-6.2 changes for AI platform teams
The Astra-Sol split gives engineering organizations a clean reason to separate application logic from model policy. Applications should describe the work—risk, deadline, context requirements and acceptance criteria—while a platform layer selects the model and processing tier. That layer should also attach evaluation metadata, enforce budgets, manage fallbacks and preserve an audit trail.
It is tempting to expose a simple “premium” switch to product teams. A richer contract will age better: declare a task class, maximum latency, maximum cost, required tools and whether escalation is allowed. The router can then evolve as prices, models and evaluation results change without forcing every application to rewrite its integration.
GPT-6.2’s shared capabilities make this separation feasible. Because Astra and Sol support the same broad tool surface and context envelope, many workloads can move between them without changing the application’s basic execution path. That portability is the real infrastructure opportunity. The fourfold price gap supplies the economic pressure; matched interfaces supply the mechanism.
The teams that benefit most will not be those that pick the “right” model once. They will be the teams that continuously prove where additional capability pays for itself, keep large contexts under control and treat every escalation as measurable evidence. With GPT-6.2, model routing is no longer an optional optimization at the edge of the stack. It is part of the production control plane.