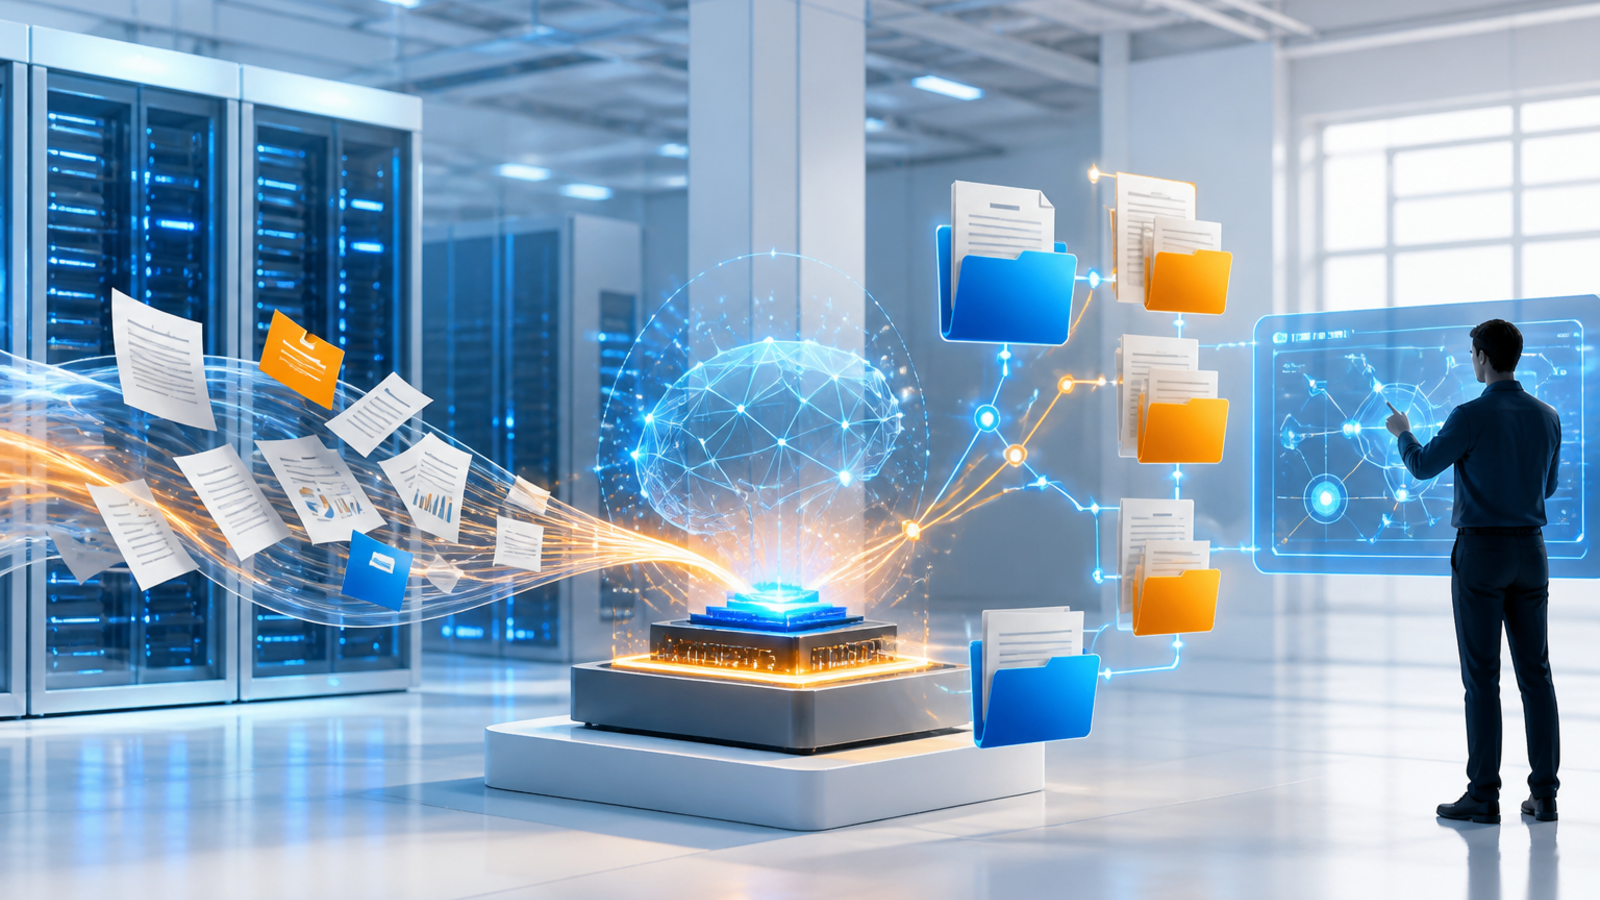
Enterprise AI agents have a retrieval problem disguised as a reasoning problem. A model may be capable of comparing contracts, reconciling financial filings, or tracing a specification across a 200-page manual, yet still fail because the right evidence never reaches its context window. Mistral’s newly introduced Agentic Search attacks that bottleneck by allowing a model to search, open, navigate, read, and grep through indexed documents in a loop instead of accepting a single batch of retrieved chunks.
The important shift is not simply “better RAG.” It is a change in where retrieval decisions happen. Traditional retrieval-augmented generation usually commits to a top set of passages before the model starts composing an answer. Agentic Search makes retrieval part of the reasoning trajectory: the model can inspect a result, decide that it needs a neighboring table or another document, and continue gathering evidence. Mistral’s early benchmarks suggest that this approach can raise correctness while reducing wasted tokens and latency. For practitioners, the larger lesson is that retrieval now needs the same budgets, observability, permissions, and evaluation discipline as every other autonomous tool loop.
Retrieval becomes an active investigation
One-shot RAG works well when an answer is likely to appear in a clean, highly ranked chunk. It is fast, predictable, and comparatively easy to operate. It breaks down when the question depends on a footnote, spans several files, requires interpreting a table, or needs evidence to be verified in its surrounding context. A vector search might identify the correct annual report but return a nearby narrative passage instead of the row containing the actual figure.
Mistral’s system separates finding a likely source from investigating it. Its search layer supplies familiar operations: search across the corpus, open a source around a hit, navigate forward or backward, read a known range, and grep for an exact term inside a document. A model can start broadly, drill into a promising result, and issue a refined search if the evidence is incomplete. Follow-up requests can exclude chunks already inspected, reducing the tendency to cycle through the same high-ranked passages.
This design matters because it preserves the value of conventional search infrastructure. Agentic Search is not a replacement for lexical, semantic, or hybrid retrieval. It is an orchestration layer above those primitives. An index still narrows the search space; the agent determines where to look next. That division lets teams keep a fast retrieval path for simple lookups while reserving the more expensive investigation loop for questions that genuinely need it.
The benchmark result is about tools, not just models
Mistral reports large gains on two document-heavy evaluations. On FinanceBench, which covers 150 questions over 368 SEC filings, the company says the full agentic loop reached up to 86% correctness, compared with 26.7% for one-shot RAG. The initial iterative search loop delivered the largest gain; adding document navigation improved accuracy again. Mistral also reports that navigation cut token consumption by 23.9% for Mistral Medium 3.5 and 33.7% for GLM-5.2 compared with a search-only loop.
The latency result is especially notable because tool-using agents are usually assumed to trade speed for accuracy. On FinanceBench, Mistral says navigation reduced p90 latency from 255 seconds to 154 seconds and mean latency from 108 seconds to 71 seconds. The explanation is plausible: once the agent finds the right document, walking within it can be cheaper than repeatedly performing broad searches and reprocessing overlapping results.
OfficeQA Pro presents a harder case: 133 numeric questions over 696 scanned, table-heavy U.S. Treasury Bulletins. Mistral reports that GLM-5.2 reached 51.9% with the full loop, up 45.6 percentage points from one-shot RAG, while Mistral Medium 3.5 gained 27.1 points. Those numbers still leave substantial room for error, which is an important caution for regulated or high-stakes workflows. Yet they reinforce the core claim: retrieval scaffolding can materially change the performance of the same underlying model.
These are vendor-run benchmarks using Mistral’s default Search Toolkit configuration, and teams should treat them as evidence to reproduce rather than guarantees. The evaluations are also narrow: long financial and government documents reward navigation in ways that short support articles may not. Still, the comparison isolates an operationally useful insight. Model selection is only one lever. The available tools, the order in which an agent uses them, and the mechanisms that prevent redundant work can have comparable impact on end-to-end quality.
Why the architecture fits enterprise agents
Search Toolkit, released separately in public preview, provides the foundation beneath Agentic Search. It combines ingestion, indexing, retrieval, and evaluation in a composable, open-source framework that can run in cloud or on-premises environments. It supports sparse BM25 retrieval, dense vectors, and hybrid configurations, with Vespa used in the starter application. The navigation tools are exposed through an MCP server, allowing any compatible agent to discover and call them.
That packaging addresses two enterprise constraints. First, sensitive data often cannot be copied into a vendor-controlled corpus. A self-hosted index keeps the document plane inside an organization’s isolation boundary, although teams must still assess where model inference occurs and what content crosses that boundary. Second, enterprises rarely have a single knowledge source. They have file stores, wikis, support systems, repositories, and structured applications with different ownership and freshness requirements. A common tool interface can give agents a consistent way to inspect indexed documents without pretending that every source is identical.
The use of MCP also makes retrieval less tightly coupled to one model. Mistral says its results showed similar patterns with Mistral Medium 3.5 and GLM-5.2, and its documentation describes the tools as usable by other MCP-compatible agents. That portability could let teams improve reasoning models without rebuilding the index, or improve retrieval logic without rewriting the agent. In practice, portability will depend on how reliably each model follows the search protocol and how much vendor-specific prompting remains embedded in the server instructions.
Agentic retrieval creates a new control surface
Giving a model permission to investigate a corpus introduces autonomy, and autonomy introduces variance. The same question may trigger three calls on one run and twelve on another. A broad query can cross business-unit boundaries. A retrieved document may contain malicious instructions intended to redirect the agent. A stale index can produce a well-cited but obsolete answer. These are not reasons to avoid agentic retrieval; they are reasons to operate it as a governed subsystem.
Platform teams should add explicit controls before putting the loop behind customer-facing or decision-making applications:
- Set hop, time, and token budgets. Cap searches and navigation steps by task class, with a clear failure mode when the agent cannot gather enough evidence.
- Authorize at query time. Filter both retrieval and document navigation using the requesting user’s identity. Index access alone is not a sufficient permission model.
- Preserve an evidence trail. Record queries, source identifiers, offsets, tool results, exclusions, and the passages ultimately used. An answer citation is less useful without the trajectory that produced it.
- Treat retrieved content as untrusted. Apply prompt-injection defenses and keep document text from changing tool permissions or system policy.
- Expose freshness and provenance. The agent should know when a source was indexed, whether extraction was complete, and which version it inspected.
Observability should distinguish retrieval failures from reasoning failures. If the correct evidence never appeared in any tool result, tuning the final prompt will not solve the problem. If the correct passage was retrieved but ignored, reranking may be irrelevant. Teams need traces that connect the initial query, each tool choice, returned chunks, final citations, latency, and cost. That makes it possible to evaluate the system by failure class instead of relying on a single answer-quality score.
A practical adoption path
The safest starting point is a corpus where navigation is clearly valuable and mistakes are reviewable: financial research, policy manuals, technical documentation, or contract analysis with a human in the loop. Build a test set from real questions, including cases that require adjacent context, exact phrases, and evidence across multiple documents. Measure one-shot hybrid retrieval first, then add the agentic loop and compare answer correctness, citation validity, tool calls, tokens, and tail latency.
Routing is more important than enabling the loop everywhere. Direct lookups over short documents should stay on the conventional path. Mistral itself recommends indexed retrieval for simple, predictable, high-volume searches. A classifier or rule-based gate can reserve agentic investigation for ambiguous questions, multi-document comparisons, or requests that explicitly require verification. This keeps average costs under control and makes the system’s behavior easier to explain.
Operators should also tune the loop rather than accepting unlimited exploration. Use exclusion lists to prevent repeated chunks, scope searches to a known source when possible, prefer grep when the target term is known, and limit the number of passages returned per hop. Semantic caching can eliminate repeated work across similar questions, but cached trajectories must respect permissions and document freshness.
Finally, evaluate with the model and corpus that will run in production. Mistral’s results indicate that navigation benefits more than one model, but different models vary in tool selection, stopping behavior, and citation discipline. Domain documents vary even more. A scanned table, a source-code repository, and a collection of HR policies demand different extraction and ranking choices. Agentic Search reduces dependence on perfect initial chunking; it does not eliminate the need for high-quality ingestion, access controls, or representative evaluation.
The larger shift: context engineering becomes runtime behavior
RAG originally framed context assembly as a preprocessing and retrieval problem. Teams selected chunk sizes, embeddings, top-k values, and rerankers, then handed the resulting bundle to a model. Agentic Search makes context assembly dynamic. The model participates in deciding what belongs in its context and can revise that decision as evidence accumulates.
That approach is likely to spread because it aligns retrieval with how complex work is actually performed: locate a promising source, inspect it, follow a reference, verify a number, and stop when the evidence is sufficient. Mistral’s release provides a concrete implementation with open components and standard tool interfaces, while its benchmark data offers a useful hypothesis for teams to test.
The takeaway is not that every RAG application now needs an agent. It is that agents working on difficult documents need a retrieval loop designed for investigation, and that loop must be bounded and measurable. The organizations that benefit most will not be those that allow the longest autonomous searches. They will be those that can prove when additional retrieval improves an answer, control which evidence an agent may inspect, and stop the investigation when the value of another tool call falls below its cost.